

What the redirect checker shows
This URL redirect checker requests the address you enter and does not follow the redirect on its own. It records the HTTP status code and the Location header, then requests the next URL, one hop at a time, until a page answers without a redirect. The result is the full redirect chain, the time each request took, and the final URL.
Each hop also lists a few response headers: content type, server, cache control, X-Robots-Tag, Strict-Transport-Security, and a Link header with a canonical URL when the server sends one.
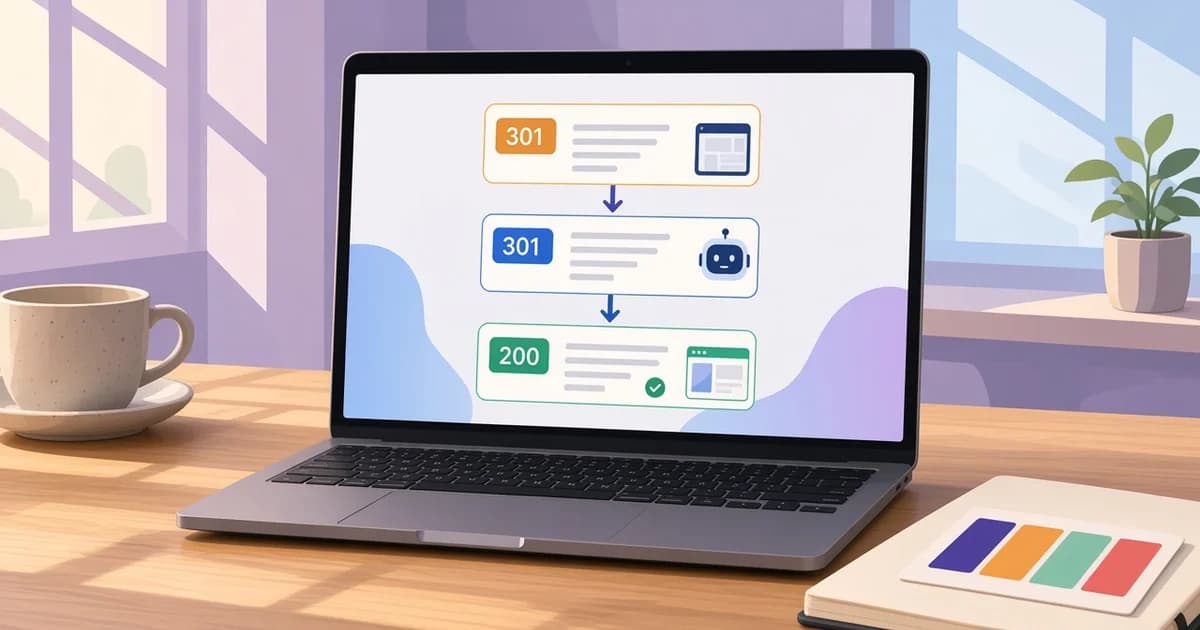
301, 302, and other status codes
A 301 redirect checker answers one question first: is the move permanent? A 301 or 308 says the old URL has been replaced. A 302 redirect, a 303, or a 307 says the move is temporary. The checker marks temporary redirects so a 302 left over from a migration is easy to find. The guide to 301 vs 302 redirects explains when each one fits.
A final status of 200 means the chain ends on a working page. A 404, 410, or 5xx at the end is reported, because visitors and crawlers who follow the redirect land on an error.
HTTP/1.1 301 Moved Permanently
Location: https://www.example.com/new-page

<!-- A meta refresh redirect in the HTML -->
<meta http-equiv="refresh" content="0; url=https://www.example.com/new-page">
Meta refresh and JavaScript redirects
Some pages answer 200 and send the visitor on from the HTML instead. The checker follows a meta refresh tag and a Refresh response header, and labels that hop so it is clear the redirect is not an HTTP one. A page that refreshes to its own address is treated as the final page, not as a loop.
JavaScript is not run. The final page is scanned for common redirects with a literal address, such as window.location.href = "..." or location.replace("..."). When one is found, the address is reported but not followed, because the script may only run under a condition the check cannot see.
Redirect chains, loops, and https
A redirect chain is more than one hop between the first URL and the final page, for example http to https, then to the www host, then to a new path. Each hop is another request. Pointing the first URL straight at the final address removes the extra steps.
To find every internal link on a site that still points at a redirect, crawl it with the sitemap generator. Its Redirects list shows linked URLs that redirect, so each link can be pointed straight at the target.
A redirect loop is a chain that comes back to a URL it already visited, so the page never loads. The checker stops as soon as a URL repeats, and also stops after 10 requests.
The notes also say when an http address forwards to https, when a hop drops from https back to http, and when the chain ends on a different host from the one you entered.
Bulk redirect checker for up to 1,000 URLs
After a site move or a change to URL structure, the old addresses need checking as a group. Switch to Bulk check and paste up to 1,000 URLs, one per line, from a spreadsheet, a redirect map, or a list of old links. Blank lines, lines that start with #, and repeated URLs are skipped.
Each URL is followed exactly as in a single check, with the same user agent for the whole list. The bulk redirect checker shows the status codes of every hop in one line, such as 301 → 301 → 200, the final URL when it differs, and notes on chains, temporary redirects, and error pages. Filters pick out redirects, chains, temporary redirects, and errors, and the Details button opens the full chain with headers. The Download CSV button saves the URL, final URL, final status, number of redirects, status chain, and notes for every row.
Check redirects as a browser or a bot
Some sites send mobile visitors, crawlers, or link preview bots to a different place. The user agent list includes desktop and mobile browsers, the Googlebot user agent for desktop and smartphone, Bingbot, and the crawlers used for Facebook, X, and LinkedIn link previews. The request still comes from the OG Scope server, so a site that verifies crawlers by IP address can answer differently from how it answers the real bot.
When a shared link shows the wrong card, check the redirect as the matching crawler first, then open the final URL in the Open Graph checker to read the tags the card is built from. The og:url guide explains how the canonical address and og:url should match the final URL.
Limits of the check
- Only public http and https addresses are requested. Localhost and private network addresses are refused, at the start and on every hop.
- No cookies are sent and no login is kept, so redirects that depend on a session are not seen.
- Redirects based on country or IP address follow the location of the server, not yours.
- JavaScript redirects are detected by pattern only and are not followed.
- A bulk check takes up to 1,000 URLs at a time and lists the results 100 at a time. Large lists are checked in small batches, so 1,000 URLs take a few minutes, and the check pauses when the rate limit for a network is reached.
- Results are not saved. Each check is a fresh request.