Guide
Canonical Tags: When They Should Match the Page URL
When a canonical link should repeat the page URL, which differences count as a canonical URL mismatch, and what the meta tag checker reports.
By Abid Ali, maintainer of OG Scope
Published
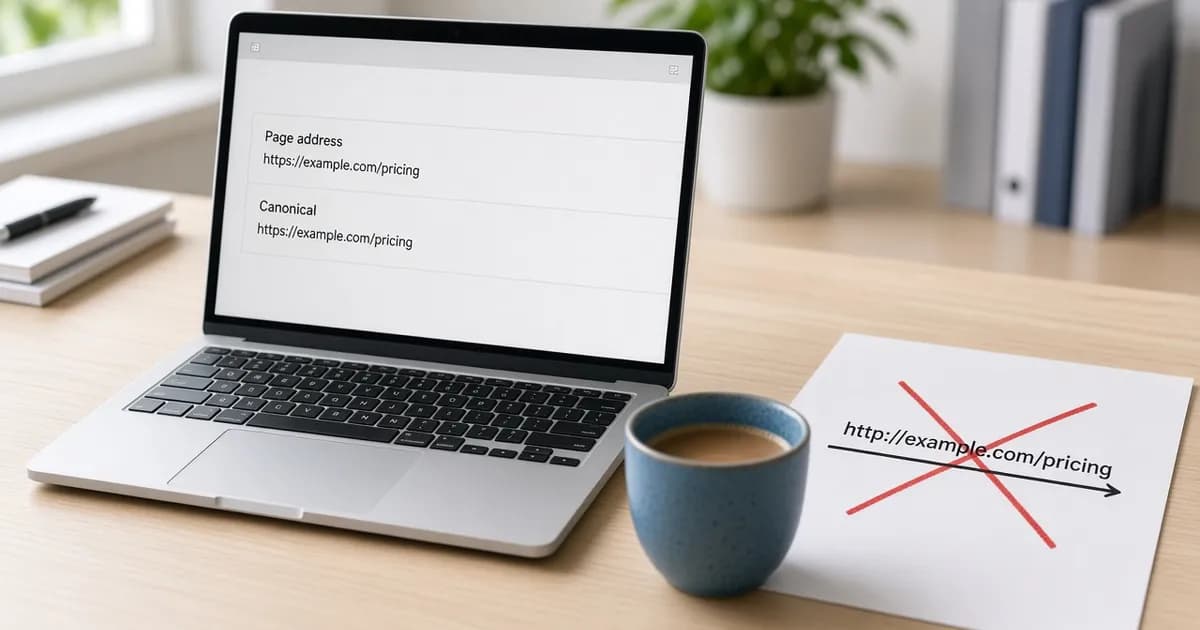
A canonical URL mismatch is a rel="canonical" link whose address is not the address of the page you meant to prefer. On a page that stands alone, that preferred address is the page itself. On a duplicate, it is the one URL that should represent the set. The canonical tag is a hint in the HTML, not a switch that forces indexing.
Google's canonical documentation, last updated 10 July 2026, lists three ways to state a preference. A redirect is a strong signal that the target should become canonical. A rel="canonical" link is also a strong signal. Listing the URL in a sitemap is a weaker signal. Using more than one of those methods helps only when they name the same URL. The same page should not carry one address in the link and a different address in the sitemap.
What the link element says
The element sits in the head and uses an absolute href. Google supports a relative path and recommends against it, because a relative href can point at a testing host if that host is crawled. A fragment, the part after #, is not a supported canonical. Google generally does not support URL fragments for this purpose.
A pricing page that prefers itself looks like this:
<link rel="canonical" href="https://www.example.com/pricing" />Google recommends that same self referencing canonical on the canonical page, not only on the duplicates. The element counts when it appears in the head, so the head needs to be valid HTML. A rel="canonical" link that also carries hreflang, lang, media, or type is ignored for canonicalization. Alternate versions use rel="alternate" instead.
The same hint can be sent as an HTTP Link header. Google supports that header for web search, including non-HTML files such as a PDF, and says to pick the element or the header rather than both. Two methods on one response are supported, and they are easier to get wrong when the two URLs drift apart.
When the href should be the page URL
Use the page's own final URL when that page is the one you want people to reach. Write the https address, the host you keep, the path, and the trailing slash you keep. Leave off tracking parameters and a fragment. HTTP, HTTPS, and www is the check for which of the four host and protocol addresses is the final one. The canonical href should be that final address, not one of the three that redirect to it.
Google prefers an HTTPS URL over the HTTP URL of the same page, unless something argues the other way: an invalid certificate, insecure dependencies other than images, a redirect from HTTPS through HTTP, or a canonical link on the HTTPS page that points at the HTTP page. That last case is a canonical URL mismatch you can see in the tag. An HTTPS page should not name the HTTP address as its preferred URL.
A script that inserts the link after the page loads makes the preference harder to read. Google's documentation says the clearest setup is a canonical URL in the HTML source, with JavaScript left so it does not change that element. If the source cannot contain it, leave the source without the element and set it only with the script, rather than publishing two different values. The guide to JavaScript meta tags is about share cards that miss tags added after the first response. The same source check applies to this link.
When a different URL is the point
A duplicate should not point at itself. Google's own example is a product that can be opened at a clean path and again through a URL with a gclid parameter. The preferred URL is the clean one, and the parameter URL's canonical link names that clean address. Signals such as links can then consolidate on one URL, and Googlebot spends less time on the copies.
That difference is intentional. The fetched address and the href disagree, and they should. The same pattern fits a print view, a tracking campaign, or an HTTP URL that still responds and should name the HTTPS page. It does not fit an article whose href is the homepage, a different article, or a staging host.
noindex is the wrong tool for choosing among copies on one site. Google says that tag blocks the page from Search, and that the canonical link is the preferred way to name one version. Within an hreflang set, the canonical page should be in the same language, or the closest substitute when that language has no canonical page of its own.
Mismatches that are usually accidental
The common accident is one href copied onto every template. A pricing page then claims the homepage is the preferred URL:
Page fetched:  https://www.example.com/pricing
Canonical:     https://www.example.com/
Search engines are being told that the homepage represents the pricing page. Internal links should also use the preferred URL. Google says consistent links to the URL you consider canonical help it understand the preference. A site that links to the parameter copy, while the tag names the clean path, is sending two preferences.
Protocol is the next accident. The visitor is on HTTPS, and the tag still names HTTP:
Page fetched:  https://www.example.com/pricing
Canonical:     http://www.example.com/pricing
A path that differs by a slug, a locale folder, or a query is the same class of problem when the page is not a duplicate of that other URL. A staging host in the href is a preference for a host you do not want in results. A redirect is the method Google describes for retiring a duplicate, and it is a stronger signal than the link. Use a redirect when the old URL should stop being a page, and use the link when both URLs should keep responding and one of them is preferred.
What the checker compares
The meta tag checker reads the first rel="canonical" link in the HTML. A relative href is resolved against the page that was fetched, or against a base href when the page has one and that base is a public http or https URL. The row then compares the resolved href with the final URL after redirects.
If the two addresses differ, the row says the canonical URL points at a different address than the page that was fetched. Protocol counts, the path counts, and the query string counts. A leading www. is ignored, and a trailing slash on the path is ignored. So an HTTP href on an HTTPS page is flagged, a homepage href on an article is flagged, and a ?ref= href on the clean page is flagged. A www-only difference is not flagged, and neither is a trailing slash on its own. Those two still belong in the href you chose. Compare the strings, because the row will stay quiet.
A relative href that resolves to the fetched page does not get the different-address note. Write the absolute https URL anyway. A value that cannot be resolved and is not an absolute http or https URL gets the note that it is not an absolute URL. The row shows the first canonical link in the HTML.
The note is a comparison, not a judgment that the tag is a mistake. On a tracking URL, a different address is what you want, as long as the href is the clean page. On the clean page, the same note means the tag is pointing somewhere else. Fetch the URL you care about, then read the href next to it.
og:url is a separate tag for share cards. The og:url guide covers that value. This page stays on rel="canonical". The two should still be the same string when both are present, so a social crawler and a search engine are not given two preferred addresses.
How to correct the href
- Open the public URL, not a preview that only exists in a CMS. The comparison is against the final URL after redirects.
- Decide whether this URL is the preferred page or a duplicate. A preferred page points at itself. A duplicate points at the preferred page.
- Set one absolute https href, with the host and the path you keep, and no fragment. Use the same href in the sitemap. Google says a sitemap URL is a suggested canonical, and a weaker signal than the link, so the two should not disagree.
- Remove a second method that names a different URL, whether that is another link element or a
Linkheader. - Run the URL through the meta tag checker again. A preferred page should no longer show the different-address note, apart from a www prefix or a trailing slash, which the comparison skips.
A page whose canonical names another URL can be left out of a generated sitemap on purpose. The sitemap generator records the canonical on each crawled page and can omit pages that point elsewhere. That is a list of duplicates, not a substitute for fixing a tag that points at the wrong page.
Check the live URL
Paste the page into the Open Graph checker to see the tags the server sends.
Open the Open Graph checker