Guide
Don't List noindex Pages in Your XML Sitemap
A sitemap lists URLs you want in search. A noindex page in that file asks for the opposite. Find the URL, then remove the tag or the listing.
By Abid Ali, maintainer of OG Scope
Published
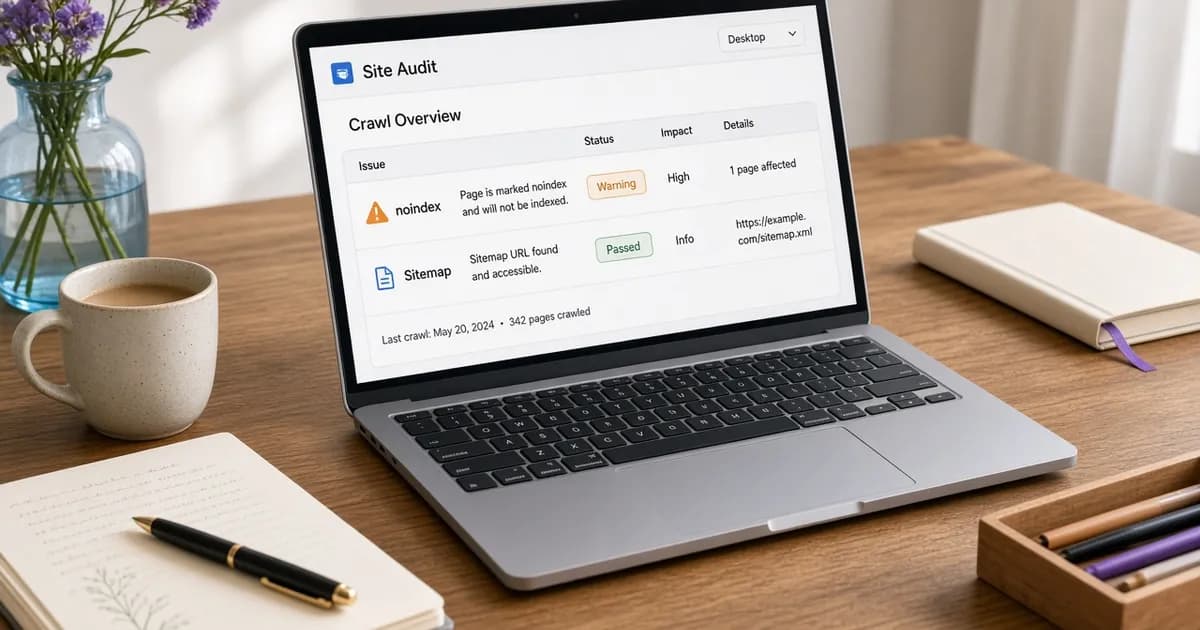
Noindex pages in sitemap listings send two opposite instructions. The sitemap says the URL is one you want in search. The noindex rule says it should not be indexed. Google's sitemap documentation tells you to include the URLs you want to see in search results. Pick one instruction and delete the other.
This page is that conflict only. It is not a full robots.txt guide, and it does not replace the steps for submitting a file.
What each signal means
An XML sitemap is a list of canonical URLs you prefer. Google's build-a-sitemap documentation, last updated 8 July 2026, says to include the URLs you want in search results, and to choose one URL when the same content exists at more than one address. Submitting the file is a hint. It does not guarantee crawling or indexing.
noindex is a separate rule. Google's noindex documentation, last updated 10 December 2025, says Google drops the page from Search results after it crawls the page and sees the rule. The rule can be a meta tag or an HTTP header. Both have the same effect.
<meta name="robots" content="noindex">X-Robots-Tag: noindexnone is also a noindex signal. A name="googlebot" tag with noindex applies to Google's web crawlers. A name="robots" tag is the broader form. The robots meta tag is what the meta tag checker reads. The header is the one to use for a file that is not HTML, such as a PDF. Google does not support a noindex rule written inside robots.txt.
For the noindex rule to be seen, the crawler has to be allowed to fetch the page. A robots.txt disallow can hide the tag. Google then may still know the URL from links, without having read noindex. That is a different mistake from listing the URL in a sitemap. Fix the disallow first if the goal is for noindex to be visible.
How Search Console reports it
Search Console's page indexing report has a reason called URL marked 'noindex'. The report says Google tried to index the page, found a noindex directive, and did not index it. If the page should stay out of search, that outcome matches the tag. If the page should be indexed, the tag has to come off.
The same help page says error spikes can follow a sitemap that includes URLs blocked by robots.txt, noindex, or a login. The sitemap filter on the report can limit the table to submitted pages, which is the practical way to see URLs that are both listed and not indexed. Open the URL, then use the inspection icon. Under indexing, the report should show that noindex is preventing indexing. Test the live URL before you assume the tag is still there.
A page that is noindex on purpose does not need to be "fixed" into the index. Google's report says it is fine for a URL to stay out when the reason is a noindex tag you meant to publish. The leftover work is to stop submitting that URL as if you wanted it indexed.
Find the conflicting URL
Start from the page indexing report when you have Search Console, or from the sitemap file when you do not. Copy one listed URL. Open it in the meta tag checker. The robots row quotes the meta tag. A noindex or none value is noted as a request not to index the page. The checker reads the HTML it fetched. It does not read an X-Robots-Tag header, so a header-only rule needs the response headers, or URL Inspection, as well.
The sitemap validator checks the file: XML, URL counts, and tags such as lastmod. It does not download every URL and look for noindex. A valid file can still list pages that ask not to be indexed. The two tools answer two questions. The validator answers whether the file is a sitemap. The meta tag checker answers whether one page carries the robots rule.
The sitemap generator has a control labeled "Leave out noindex pages", on by default. While it is on, a crawled page with noindex or none in a robots or googlebot meta tag, or in X-Robots-Tag, is left out of the download. Turn it off only when you intend to list those URLs. A sitemap exported from a CMS can ignore that choice, so check the file you actually submit. How to submit it is in the Search Console submission guide.
Remove the signal that is wrong
When the page should not be in search, delete its loc from the sitemap and leave noindex in place. Thank-you pages, internal search results, previews, and duplicate filter URLs are typical cases. Regenerating the file is safer than hand-editing a generated sitemap, because the next export would put the URL back.
When the page should be eligible for search, remove the meta tag or the header and keep the sitemap line. Then confirm the live HTML no longer contains noindex. A template that adds the tag on every page, including the ones in the sitemap, will recreate the conflict on the next render.
Canonical URLs belong in the sitemap, not every duplicate. If two addresses serve the same page, list the one the canonical link names. The canonical tag guide covers when that link should match the fetched URL. A noindex on the duplicate, plus a canonical to the preferred URL, is a common pair. The preferred URL is the one that stays in the sitemap, and it should not carry noindex.
After the file changes, resubmit that sitemap so Search Console reads the new list. Removing the sitemap entry from the report does not make Google forget URLs it already fetched. noindex still has to be crawled before the page drops. Google notes that a revisit can take a long time on a page that is rarely fetched. URL Inspection can request indexing for a page whose noindex tag you removed.
Check the live URL
Paste the page into the Open Graph checker to see the tags the server sends.
Open the Open Graph checker