Guide
Redirect Chains and Loops: How to Find and Fix Them
How to read each hop in a redirect chain, when to collapse it to one 301, and how a redirect loop repeats a URL so the page never loads in a browser.
By Abid Ali, maintainer of OG Scope
Published
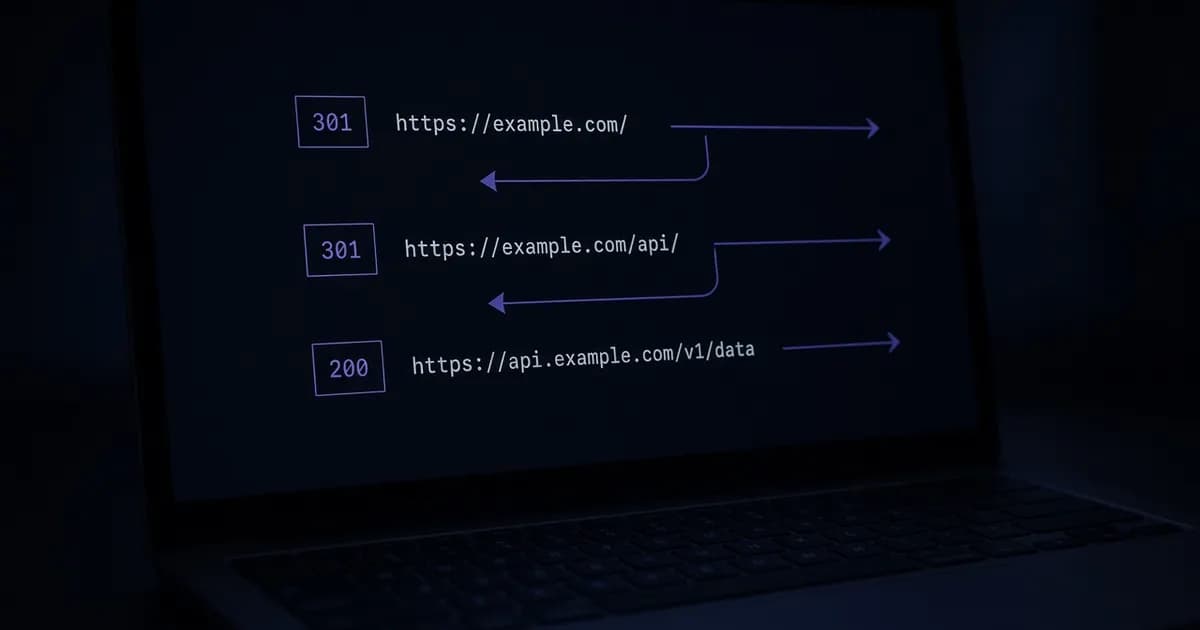
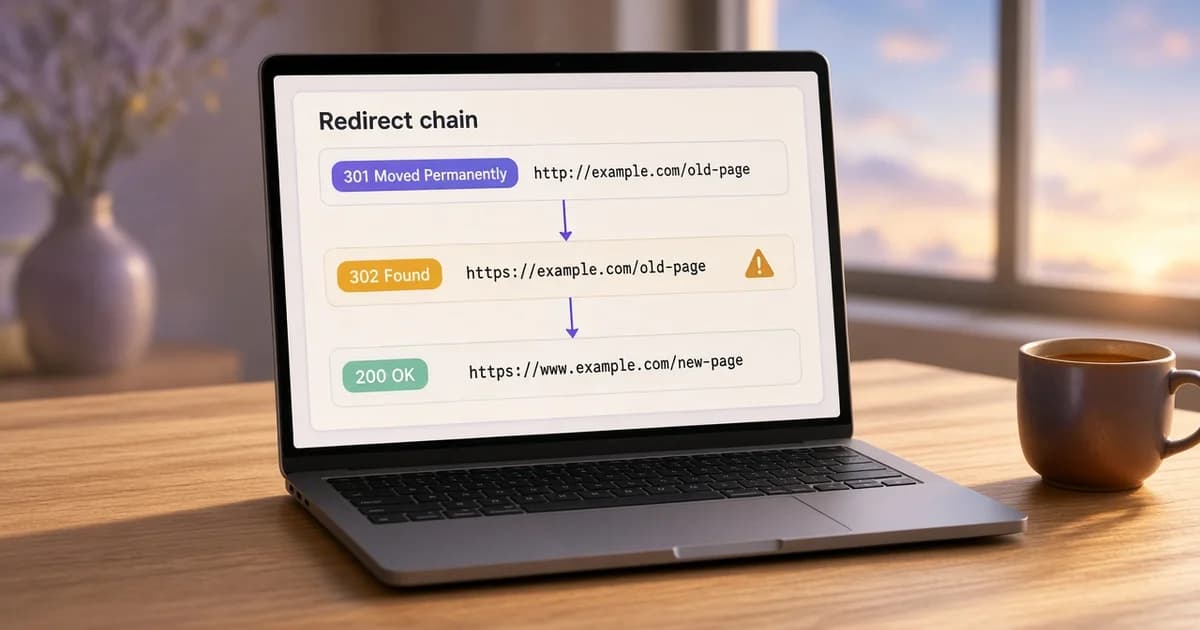
A redirect chain is two or more hops between the URL you opened and the page that finally loads. Each hop is another request. A redirect loop is a chain that comes back to a URL it already visited, so no finished page is ever returned. The status codes themselves, and when a single hop should be permanent or temporary, stay on the 301 vs 302 guide.
Paste the first URL into the redirect checker. The hop list is the thing to read. A short note on that tool page names chains, loops, and https. This guide is how to read the rows and what to change on the server.
How to read the hop list
A chain of two permanent hops looks like this:
1  301  https://example.com/old
2  301  https://www.example.com/old
3  200  https://www.example.com/new
Row 1 is the address you entered and the status it returned. A 301 or 302 means that response did not serve the page. It named the next URL. Row 2 is that next request. Row 3 is a 200, so the chain ended and that URL is the page a browser would show. The final URL is the one that matters for the content, the canonical address, and a shared link.
Count the rows whose status is a redirect, not the final 200. Two redirect rows means two hops. The first URL in the example never needs to stop on www.example.com/old. That middle address exists only because an older rule is still in place.
A status in the middle that is not a redirect is a break in the chain. A 404 or a 500 on row 2 means the Location from row 1 names a URL that does not exist or did not answer. Fix that target, or point row 1 at the real final URL, before you look at any later hop.
Also read the scheme and the host on every row. A hop from http:// to https://, then from the apex to www, then from an old path to a new path, is three separate rules stacked on one visit. The checker notes when a hop drops from https back to http, and when the chain ends on a different host from the one you entered.
When a redirect chain should be one hop
Google's site-move documentation says to avoid chaining redirects. Googlebot can follow up to 10 hops, and the advice there is to send the first URL to the final destination directly. When that is not possible, keep the chain low: ideally no more than 3, and fewer than 5. Extra hops add latency, and not every browser or crawler will follow a long chain.
Collapse the example by deleting the middle rule. The first URL should answer once:
301 https://example.com/old → https://www.example.com/newUse a 301 or a 308 when that old address should stay at the new one. Leave a 302 in place only when the move is temporary. After the rule is published, request the first URL again. The list should be one redirect and then a 200 on the final URL. Internal links that still point at the old address can be found with the sitemap generator: its Redirects list is the set of linked URLs that do not answer directly.
What a redirect loop looks like
A loop does not end in a 200. A URL that already appeared shows up again:
1  301  https://example.com/pricing
2  301  https://www.example.com/pricing
3  301  https://example.com/pricing
Row 3 is the same address as row 1. The checker stops there, with the finding Redirect loop, and it names the URL that appeared more than once. It will not keep walking. It also stops after 10 requests even when no URL has repeated, and that result is labeled More than 10 redirects. Browsers give up on a chain that long as well. Chromium shows that failure as ERR_TOO_MANY_REDIRECTS. That message is too many redirects, not a server outage: the host is answering, and each answer points onward.
A meta refresh that names the same address is the finished page, not a loop. The checker stops there and does not request it again. A script that sets the page location is reported and not followed, so a JavaScript hop never appears as another row in the list.
Rules that send the chain backward
A loop is two rules that disagree about the one URL a path should have. The hop list does not say which layer sent the response. A host setting for the preferred domain, a rewrite in the web server, and a redirect list in the CMS can all answer the same path. Change one of them, request the first URL again, and see which row disappeared. Typical pairs:
- The http host redirects to https, and a second rule redirects https back to http.
- The apex redirects to www, and www redirects to the apex.
- A trailing-slash rule and a no-slash rule each send the path to the other form.
- The web server sends a path to one address, and the CMS sends that address back, often because a canonical setting and a host rule name different hosts.
Fix one side so both rules agree on the final URL, then remove the other hop. Changing only the CMS, or only the server, leaves the opposing rule in place and the loop returns. Check the same URL as a browser and as Googlebot when a site sends crawlers somewhere else. The request still comes from this site's server, so a host that checks crawler IP addresses can answer differently from the real bot.
Check the first URL again
After the rule change, run the original address, not the final one. A clean result is a single 301 or 308 to the final URL, then a 200. A 200 on the first row means that URL no longer redirects. A repeated URL means the opposing rule is still published. A chain of http, then www, then a new path still has extra hops to remove.
Check the live URL
Paste the page into the Open Graph checker to see the tags the server sends.
Open the Open Graph checker